What SPACE actually provides, how its control and command paths differ, the reported red-team results, local deployment requirements and security questions for adopters.
An evidence-led comparison of GitHub AI Scan and agentic autofix: coverage, branch limits, merge blocking, prerequisites, billing and a practical rollout plan.
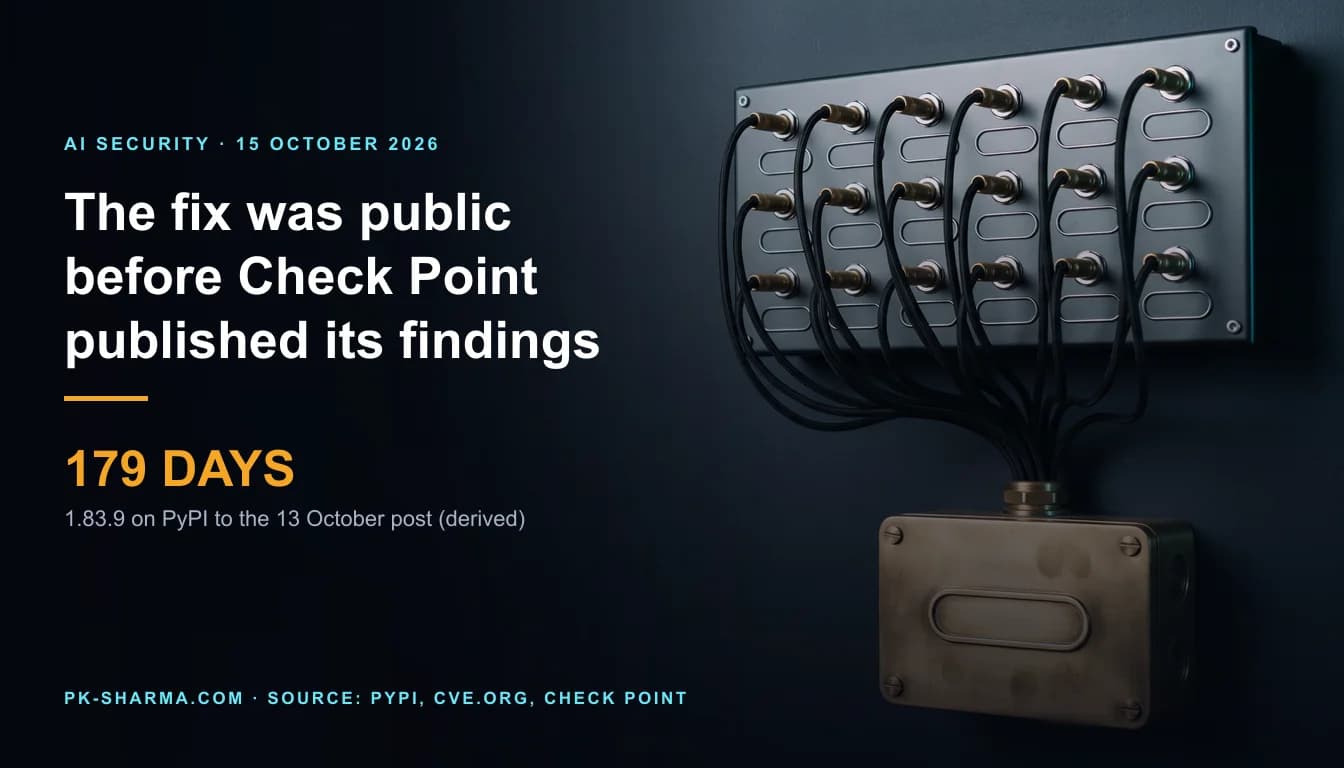
What Check Point, LiteLLM, CVE.org, PyPI, CISA and independent researchers say about two LiteLLM gateway flaws: the dates, the versions, who needs what access, what exploitation is reported, UK controls and a ranked checklist. Defender level only.
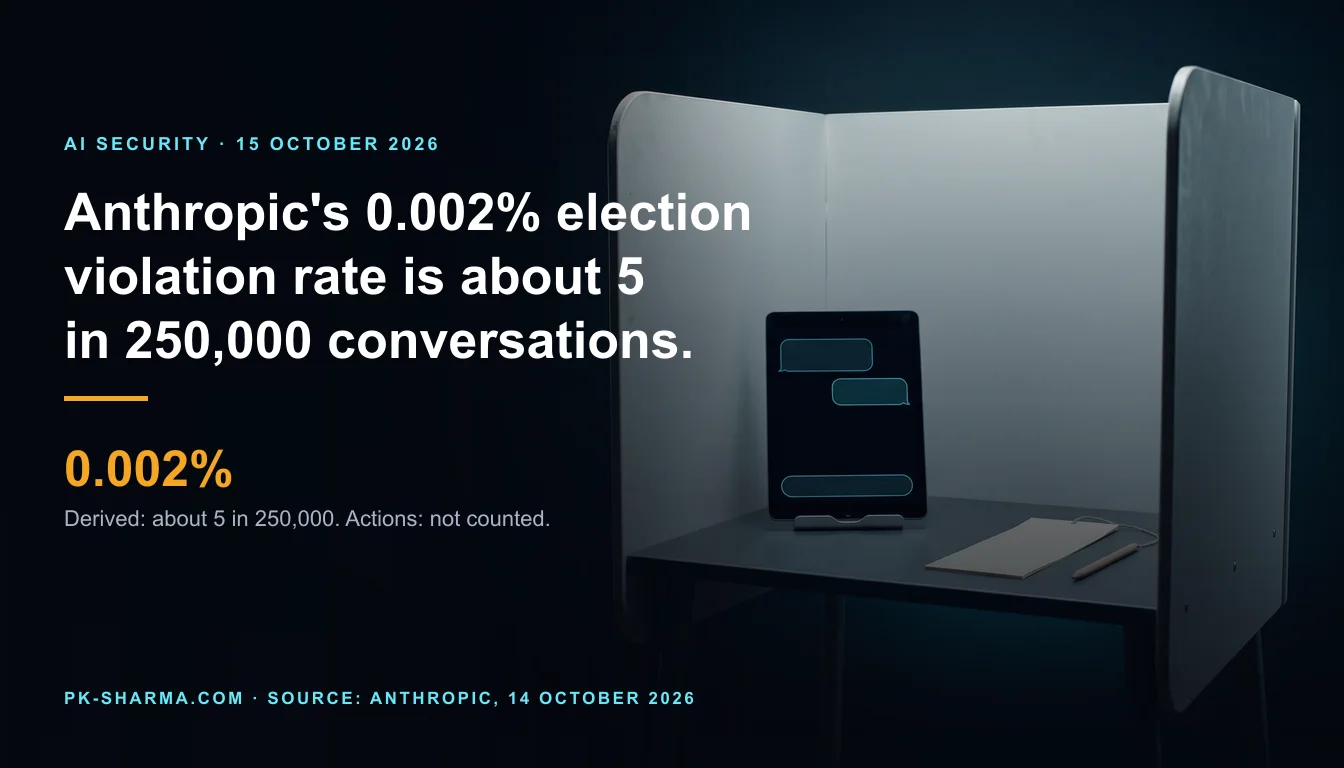
What Anthropic's 14 October 2026 post establishes about election use of Claude and what it leaves out: the arithmetic behind 0.002%, the 99% beside 85% on the same cards, where UK rules stop for chatbots, and checklists for election teams, communications leads and companies.
What HiddenLayer's two pages print for Jev, what they leave out, the arithmetic on the one count they give, an independent preprint on the same version, TypeSafe's claims against its own documentation, what UK guidance says, and a ranked checklist. Defender level only.
Noma's SneakPeek dates computed from its blog and press release, which disagree on the first fix; what Anthropic's changelog and advisories say, which versions are fixed, whether auto-update applies, UK controls and an ordered checklist.
What XBOW's pages, Google's release notes, rules page and public tracker, and OpenAI's model pages establish about a six-day Chrome chain, what they leave out, the arithmetic, UK patch clocks and the Computer Misuse Act as read, and a ranked checklist.
What Nvidia's release and the Guardian's report establish about the $250 million pledge, the arithmetic against AISI's budget and Nvidia's own results, what is not stated, what UK guidance says about accepting vendor money, and an ordered checklist.
What Anthropic's page shows and does not show on small-model self-replication: the speed on real TV boxes, 4 of 5 runs on emulated devices, SecurityWeek checked against it, The Register's critique beside Anthropic's case, UK controls and a ranked checklist. Defender level only.
What OpenAI and the three researchers each state, the dates drawn to scale, what neither states, what METR's own record shows, who holds the key to outside monitors, what UK pages say, and an ordered checklist for a customer and a board.
What Booz Allen's page and white paper establish about an AI test in its OT lab, what they leave out, the arithmetic behind 8 of 8, how the UK AI Security Institute's industrial range and the NCSC compare, what UK guidance covers, and a ranked checklist. Defender level only.