Voxtral 3: independent test puts Small at 2.1% speech error, while live-agent limits need scrutiny
Mistral's new voice stack spans transcription, speech generation and an agent SDK. Independent testing supports a strong batch-transcription result, but the price, latency and feature limits differ sharply by mode.
By Parminder Kumar Sharma · · 9 min read
The measured result, and its limit
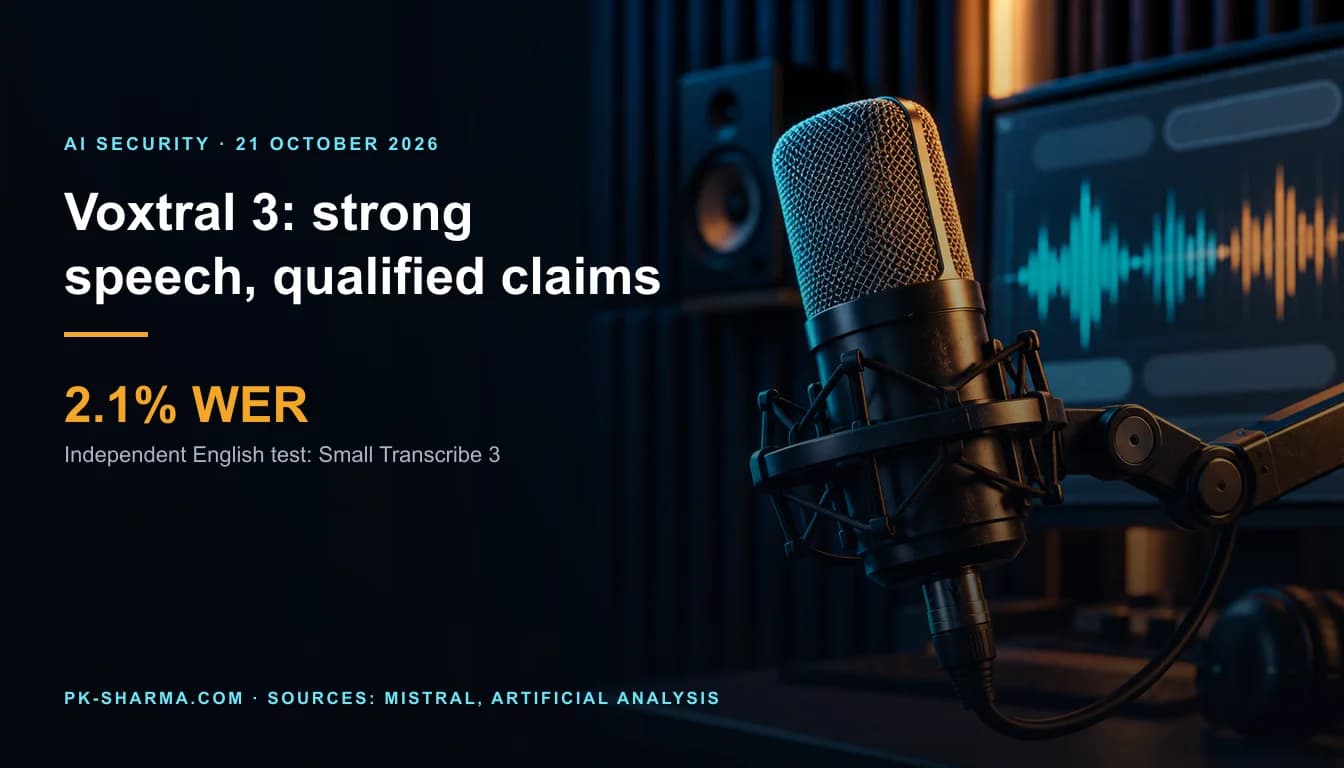
On Artificial Analysis's independently run non-streaming test, Voxtral Small Transcribe 3 makes errors on 2.1% of reference words. Voxtral Mini Transcribe 3 records 2.2%. Both figures come from a weighted English test of roughly eight hours of audio, rather than Mistral's own chart. They are strong launch-day results for recorded speech. They do not measure a multilingual call-centre deployment, speech generation, a complete voice agent or whether the model will correctly carry out a business action.
Mistral's Voxtral 3 announcement covers three speech-to-text routes, text-to-speech and an agent SDK that connects listening, a reasoning model, tool calls and spoken replies. The company published model prices for each route on 20 October 2026. For a buyer, the important distinction is that transcription, live transcription, generated speech and a full agent are different services with different bills and operating limits. The family name does not tell you which one you are buying.
Five models, four jobs, six prices
The developer overview lists five models: three for speech to text and two for text to speech. The launch price table shows six charge lines because it also quotes the voice-agent API with two reasoning-model choices. A recorded-file transcript does not automatically include the spoken reply, reasoning model or tool calls. Conversely, the $0.04 and $0.08 per minute agent lines are not pure transcription prices.
Mistral's Voxtral 3 launch price table, 20 October 2026. USD list prices; no tax or contractual discount assumed.
| Route | Launch price | What it does not buy |
|---|---|---|
| Mini Transcribe 3, recorded | $0.0035 per audio minute | Reasoning, speech out or a live agent |
| Small Transcribe 3, recorded | $0.0040 per audio minute | Reasoning, speech out or a live agent |
| Mini Transcribe Realtime 3 | $0.008 per audio minute | A complete two-way voice agent |
| Mini TTS 3 | $13 per million input characters | Speech recognition or agent reasoning |
| Voice agent with Mistral Small 4 | $0.04 per minute | A guarantee of business-task success |
| Voice agent with a larger model | $0.08 per minute | A guarantee of business-task success |
A simple planning calculation makes the separate meters visible. For 1,000 recorded audio minutes, Mini transcription is $3.50 and Small is $4.00, using Mistral's listed per-minute prices. The same duration at the listed full-agent rates would be $40 or $80. Those are illustrative list-price multiplications, not like-for-like invoices: a two-way conversation has additional generated audio and a different workload. For TTS, one million billed characters at the listed rate is $13; it cannot be converted to a reliable per-minute speech cost without knowing the characters spoken, language and billing rules. Self-deployment requires a separate commercial discussion, and no on-premises total cost is published in the announcement.
Where Voxtral sits in an external comparison
Artificial Analysis tested API endpoints directly and reports a normalised USD price per 1,000 audio minutes. Its 21 October leaderboard snapshot puts Voxtral Small Transcribe 3 at 2.1% AA-WER, a 67.8 speed factor and $4 per 1,000 minutes. Mini Transcribe 3 scores 2.2%, 72.4 and $3.50 respectively. For context on that same non-streaming AA-WER measure, MAI-Transcribe-2 is listed at 2.0% and $1.67, ElevenLabs Scribe v2 at 2.2% and $3.67, and Gemini 3.5 Transcribe at 2.6% and $5. The leaderboard can move after this snapshot, and these English-weighted results do not rank full voice agents.
Artificial Analysis non-streaming AA-WER v2 and normalised API cost per 1,000 audio minutes, read 21 October 2026. Lower WER is better; prices reflect its methodology, not a full voice-agent bill.
| API model | AA-WER | Cost per 1,000 min |
|---|---|---|
| MAI-Transcribe-2 | 2.0% | $1.67 |
| Voxtral Small Transcribe 3 | 2.1% | $4.00 |
| Voxtral Mini Transcribe 3 | 2.2% | $3.50 |
| Scribe v2 | 2.2% | $3.67 |
| Gemini 3.5 Transcribe | 2.6% | $5.00 |
Mistral separately claims its own multilingual, diarisation and text-to-speech advantages. Its FLEURS chart macro-averages an intersection of 45 languages, using character error rate for Japanese, Korean, Thai and Chinese; its diarisation chart uses concatenated minimum permutation WER on public conversation benchmarks. Those are different tasks and denominators from Artificial Analysis's English-weighted AA-WER. Mistral's speech-generation charts include internal evaluations with an AI judge and a selected prompt set. They are evidence of the company's evaluation design, not independent proof that one speech voice will sound better to a particular customer or dialect group. Procurement testing should include actual call recordings and spoken outputs.
The live-session trade-off hidden by the headline
In the voice-agent architecture, the caller's speech goes to a realtime transcription model, then a separate reasoning model decides what to say or which tool to call, then a text-to-speech model talks back. The SDK uses LiveKit and supports interruptions. Mistral says a turn can complete in under one second. That is a company claim about its stack, not a measured guarantee for a deployment with real network delays, tools and customer systems. The realtime model card describes an 80 to 2,400 ms configurable streaming delay, a setting for the transcript path rather than a whole-call response time.
The launch calls out both speaker diarisation, meaning labels for who spoke, and end-of-turn detection, meaning a signal that the caller has stopped. The speech-to-text developer matrix says both features work in realtime but cannot share one realtime session: setting both returns an error. A team that needs speaker attribution and automatic turn handling simultaneously must design and test around that limitation. The same matrix says realtime results do not carry start and end timestamps for each segment; recorded-file results can carry segment timestamps, but word-level timestamps are unavailable. These details matter for call review, audit trails and subtitle products.
Language and deployment claims need a model-by-model check
Mistral's audio language specification lists 50 languages for each recorded transcription model, 45 languages and dialects for realtime transcription, and 35 languages with more than 50 dialects for text-to-speech. The launch page also describes 35-plus TTS languages. Yet the TTS 3 model card, dated 20 October, still says nine languages, as does the general model catalogue. These Mistral pages do not agree. The narrower model card does not prove that only nine work, and the broader launch promise does not identify the tested quality of every voice and dialect. Teams should confirm the exact API model ID, language, preset voice and contractual support before promising a locale to users.
What the launch and developer documentation establish, and what a buyer must still test or clarify
| Topic | On the record | Not established |
|---|---|---|
| Batch accuracy | Independent AA-WER: Small 2.1%, Mini 2.2% on its English-weighted mix | Accuracy for a particular UK accent, call channel or all supported languages |
| Realtime features | Diarisation and turn detection exist in separate session configurations | Both operating together in one session |
| TTS languages | Launch and language spec say 35-plus; model card says nine | A reconciled language and voice matrix for the model |
| Data location | EU, US and global hosted endpoints, plus quoted self-deployment | That a global request stays in the EU, or that the control plane is regional |
| Full agent | SDK joins transcription, reasoning, tools and speech | Reliable task completion, consent or safe tool authorisation |
Mistral markets a sovereign route through EU-hosted or self-deployed processing. Its regional inference documentation is more precise: the global endpoint has no regional processing commitment; the EU endpoint provides a selected processing geography, and the policy lists a 10% upcharge for input and output tokens plus cache charges. The page does not state how that token-rate rule applies to Voxtral's audio-minute or character prices. Regional inference also does not make account configuration, API keys, billing, access management or usage analytics regionally stored. The same page says stateful Agents, Batch and Files API features are not available on regional endpoints, and not every model or tool is available in every region. This creates a specific question for a voice-agent rollout: which of the voice stack, tools, storage and logs can actually stay in the required geography? Ask Mistral to demonstrate the exact configuration rather than treating 'EU-hosted' as a blanket answer.
The voice-cloning offer also needs governance. Mistral's cloning guide describes one-off zero-shot cloning from a supplied short clip and saved voices. Saved voices have a retention-notice field defaulting to 30 days, with a configurable range of one to 365 days; its professional guidance recommends 30 minutes to three hours of clean source audio. The launch's '30 minutes' is a starting point for a professional adaptation, not a guarantee that any voice, language or emotion will be reproduced faithfully. A UK organisation should establish whose voice it is entitled to use, limit who may upload reference audio or create saved voices, and record how samples and generated speech are retained.
What to test before putting a voice agent on a real line
Take this with you
Procurement and deployment sequence
- Pick the actual job first: recorded transcript, live transcript, generated speech, or two-way agent. Map every model and charge line to that job.
- Run a representative, permission-cleared test set of UK calls and languages. Score word errors, names, numbers, speaker labels, interruptions and task completion separately.
- Prototype the live-session settings. Test diarisation and end-of-turn behaviour as separate configurations, and verify whether your audit record needs missing word timestamps.
- Confirm the exact supported TTS language and preset voice against a working model ID and commercial documentation. Record the nine-versus-35 documentation conflict until Mistral resolves it.
- For tool use, require verified caller identity, least-privilege connections, explicit confirmation before irreversible actions, logs and a human escalation route.
- For regional or self-hosted use, request a data-flow and retention schedule covering audio, transcripts, reference voices, logs, control-plane metadata and third-party tools. Calculate the regional upcharge and infrastructure costs separately.
Voxtral 3 now has a credible independent result for its recorded transcription models. Whether it is the right voice agent depends on a different question: can the exact live configuration deliver the required language, speaker record, safe action and data location at the quoted end-to-end cost? The release material does not answer that for any particular organisation.
Sources
- PrimaryVoxtral 3 announcement, product claims, evaluation descriptions and launch pricesMistral AIaccessed 2026-10-21
- PrimaryIndependent non-streaming speech-to-text measurements and provider comparison, read 21 October 2026Artificial Analysisaccessed 2026-10-21
- PrimarySpeech-to-text testing method, datasets, weighting and word-error formulaArtificial Analysisaccessed 2026-10-21
- PrimaryDeveloper feature matrix and live-session diarisation versus turn-detection limitMistral AIaccessed 2026-10-21
- PrimaryVoxtral 3 language counts by modelMistral AIaccessed 2026-10-21
- PrimaryTTS model card listing nine languages, in conflict with launch and audio language matrixMistral AIaccessed 2026-10-21
- PrimaryVoice agent architecture, SDK, tools and telephony availabilityMistral AIaccessed 2026-10-21
- PrimaryRegional inference, 10% upcharge and data-location limitationsMistral AIaccessed 2026-10-21
- PrimaryVoice cloning, saved voice retention and professional reference-audio guidanceMistral AIaccessed 2026-10-21